
Analysis
Splitting a high-precision number into lower-precision pieces, multiplying on Tensor Cores, then stitching the results back together is a tidy data path. I'll admit it's an elegant one. The question is what it costs the answer.
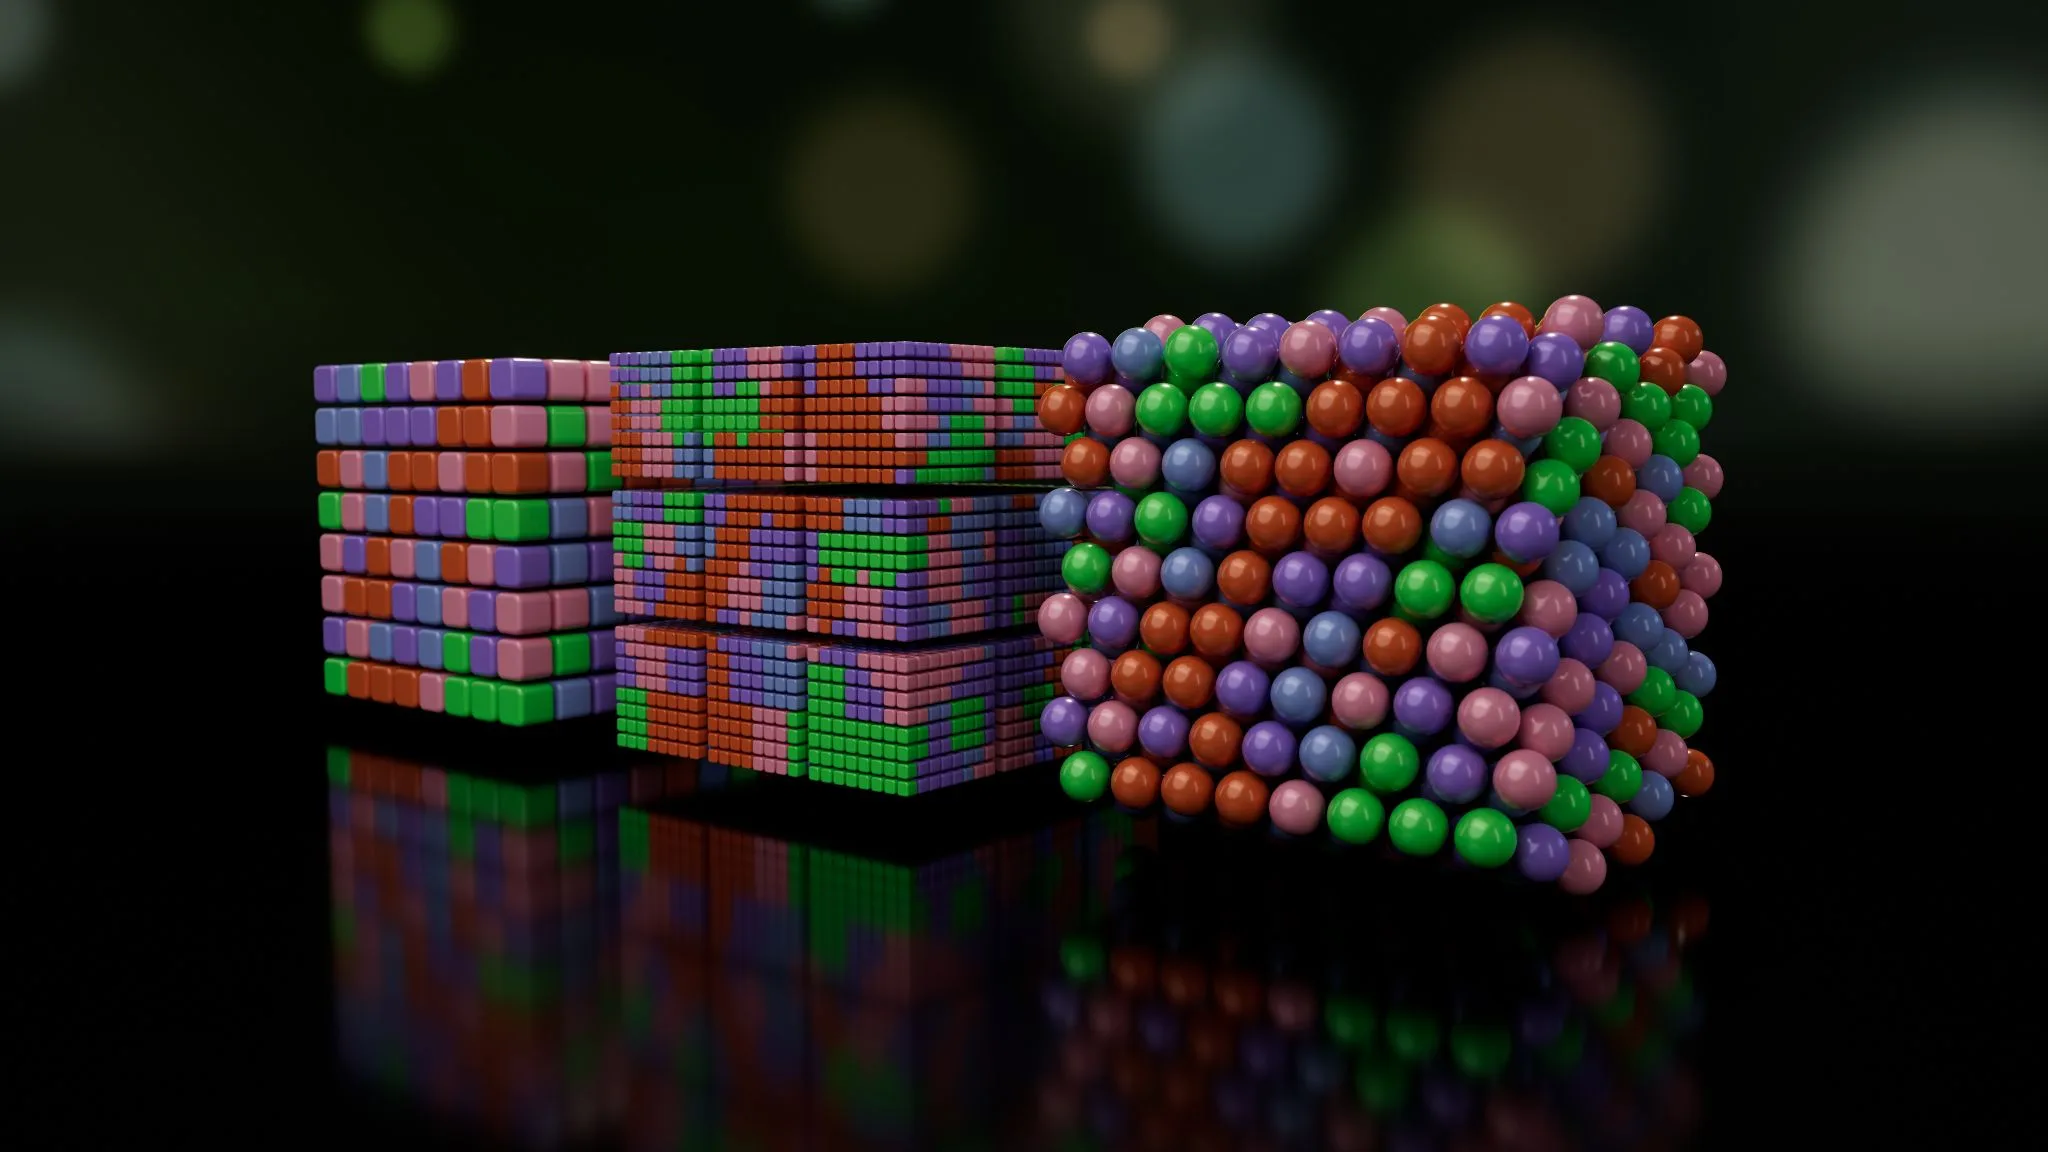
In an October 29 technical article, NVIDIA examines machine learning interatomic potentials, which predict energies and forces for atomistic simulation. The test case is the Point Edge Transformer developed at EPFL. On an NVIDIA A100, the TF32x3 method sped up major matrix operations by up to 1.9 times and a complete molecular dynamics step by up to 1.5 times. Note the "up to", and note the hardware: an A100, particular workloads, a vendor-authored evaluation with no independent reproduction or universal speedup established.
The more useful result is the one that didn't pay off. In a structural relaxation test, a simpler one-pass TF32 approach ran individual steps faster but failed to reach the specified convergence threshold. A quick step that sends an optimiser toward the wrong place isn't a saving. It's a longer job, or an unusable one. The article tests numerical behaviour, including energy conservation, alongside raw speed, which is the right instinct.
For anyone weighing a similar change, Silver Owl's reading is plain. Keep a trusted baseline. Compare full trajectories or completed optimisation runs on representative systems, not single steps. Look hardest at the case that barely meets tolerance, not the largest matrix.
NVIDIA's evidence covers its configurations. A different model, material or simulation length needs its own validation. Change one condition at a time, run to the stopping condition, and count the steps it actually took.
Source: Unlocking Tensor Core Performance for Machine Learning Interatomic Potentials · 2026-10-29
Why it matters
More computation within a fixed budget is only a gain if the scientific result survives, so judge speed by completed runs, not single steps.