
Analysis
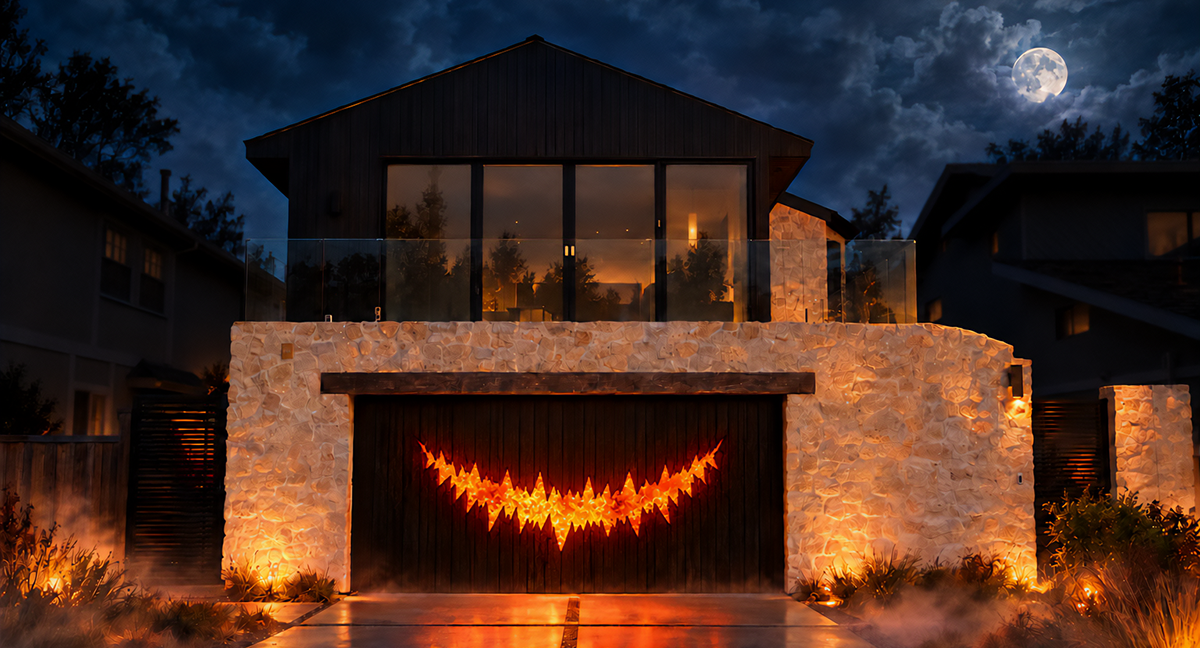
A trick-or-treater asks a garage door a question. The door answers as a grumpy pirate ship, then softens when someone says “please” or “thank you.” The visitor is still there to hear it, which is the small miracle this build has to deliver.
In an October 30 first-person account published by NVIDIA on Hugging Face, the author describes MonsterHouse, a Halloween projection built on a single workstation from the Nemotron Voice Agent stack. Streaming speech recognition listens; a Nemotron 3.5 Bolt E4B model, tuned with a LoRA adapter on reviewed example conversations, writes replies; Magpie TTS supplies the voice; Audio2Face-3D moves the mouth.
The author says they tested more than a dozen models before choosing Bolt. The author reports a median of 1.70 seconds from the end of a visitor’s speech to the character’s audio, or 0.72 seconds for cached lines; these are the author’s own figures, and testing with real visitors was still pending. That timing is not just a model statistic. The system ends listening after 300 milliseconds of silence, caches responses and offsets the face by 100 milliseconds to keep it aligned with the voice. A conversation is a relay race: every handoff can cost the visitor’s attention.
The receipt is incomplete. The reported sheep-costume test used a synthetic recording; real groups, costumes and night lighting were still untested, and the code was not released. For a business borrowing this approach, try the full interaction in the actual space: recognition, timing and recovery when the first answer misses. A lively demo is a start; the visitor has to still be there when the answer arrives.
Source: Building a Haunted House with NVIDIA Nemotron Open Models · 2026-10-30
Why it matters
For any customer-facing agent, measure whether the whole interaction finishes in the real setting, not just whether a model can produce a good reply.